Building infrastructure people can depend on.
We believe infrastructure should be powerful without being complicated. CloudForge gives developers and businesses the performance, control and reliability they need to build with confidence.
Make serious infrastructure accessible.
Enterprise-grade compute has traditionally meant long contracts, opaque invoices and weeks of procurement. We started CloudForge because a two-person team should be able to run on the same hardware, the same network and the same reliability guarantees as a company with a dedicated infrastructure department.
That means honest pricing published on the page, capacity you can provision in seconds, and engineers who answer when something needs attention. We invest in the unglamorous parts — power, cooling, peering, spare capacity — so the teams building on top of us never have to think about them.
What we hold ourselves to.
We obsess over speed and reliability.
Clear pricing and straightforward infrastructure.
Security is built into every layer.
Tools should work the way developers think.
99.99%
Uptime
50+
Global Locations
24/7
Expert Support
10K+
Servers Deployed
How infrastructure gets built here.
From the first capacity sketch to continuous scaling, each phase has clear owners, hard checkpoints and no shortcuts. Here is exactly what happens between the day we pick a location and the day your first server goes live.
01
Design
Every region starts on paper. We model power, cooling, network paths and failure domains before a single rack is ordered — capacity headroom is designed in, not bolted on.
- Capacity and growth modeling
- Redundant power and network paths
- Failure-domain isolation by design
04
Monitor
Everything is measured, all the time. Thousands of metrics per host feed alerts that reach an on-call engineer in under a minute — often before customers notice anything.
- Per-host metrics, 1s resolution
- Sub-minute alert delivery
- Public status, honest postmortems
02
Build
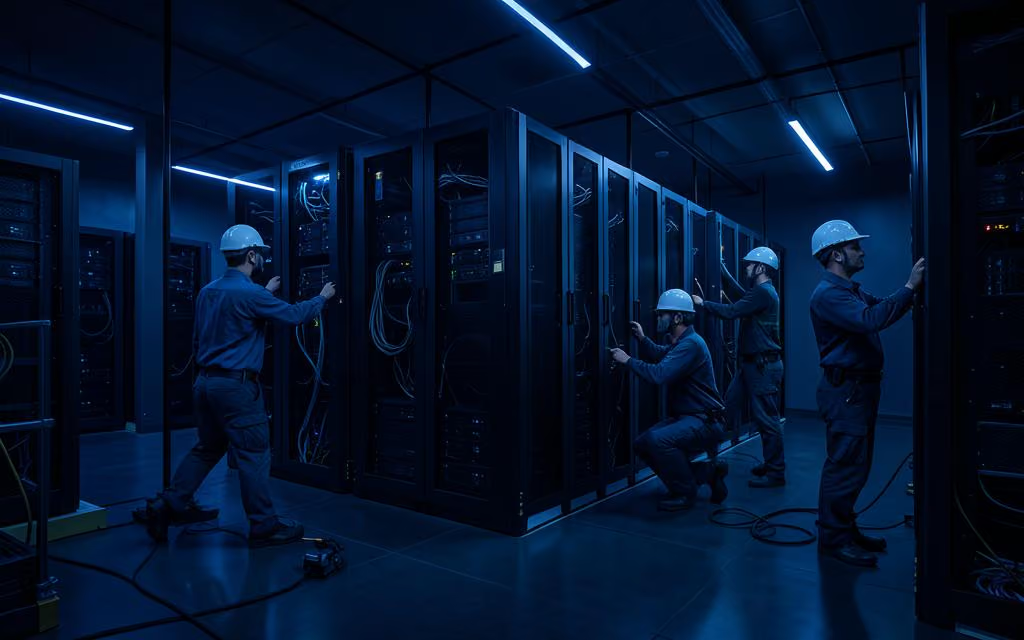
Our own engineers rack, cable and burn-in every server. Hardware is stress-tested for days under synthetic load before it ever touches customer workloads.
- In-house racking and cabling
- Multi-day hardware burn-in
- Spare capacity kept on-site
05
Scale
Growth is a continuous loop. Utilization trends feed back into the design phase, so capacity expands ahead of demand and performance never degrades as we grow.
- Demand forecasting from live data
- Rolling capacity expansion
- Same SLA at any scale
03
Deploy
Regions come online in phases. Automated provisioning, golden images and end-to-end verification mean new capacity is customer-ready in minutes, not weeks.
- Fully automated provisioning
- Golden images, zero snowflakes
- End-to-end verification before launch
Ready to start?
Provision your first server