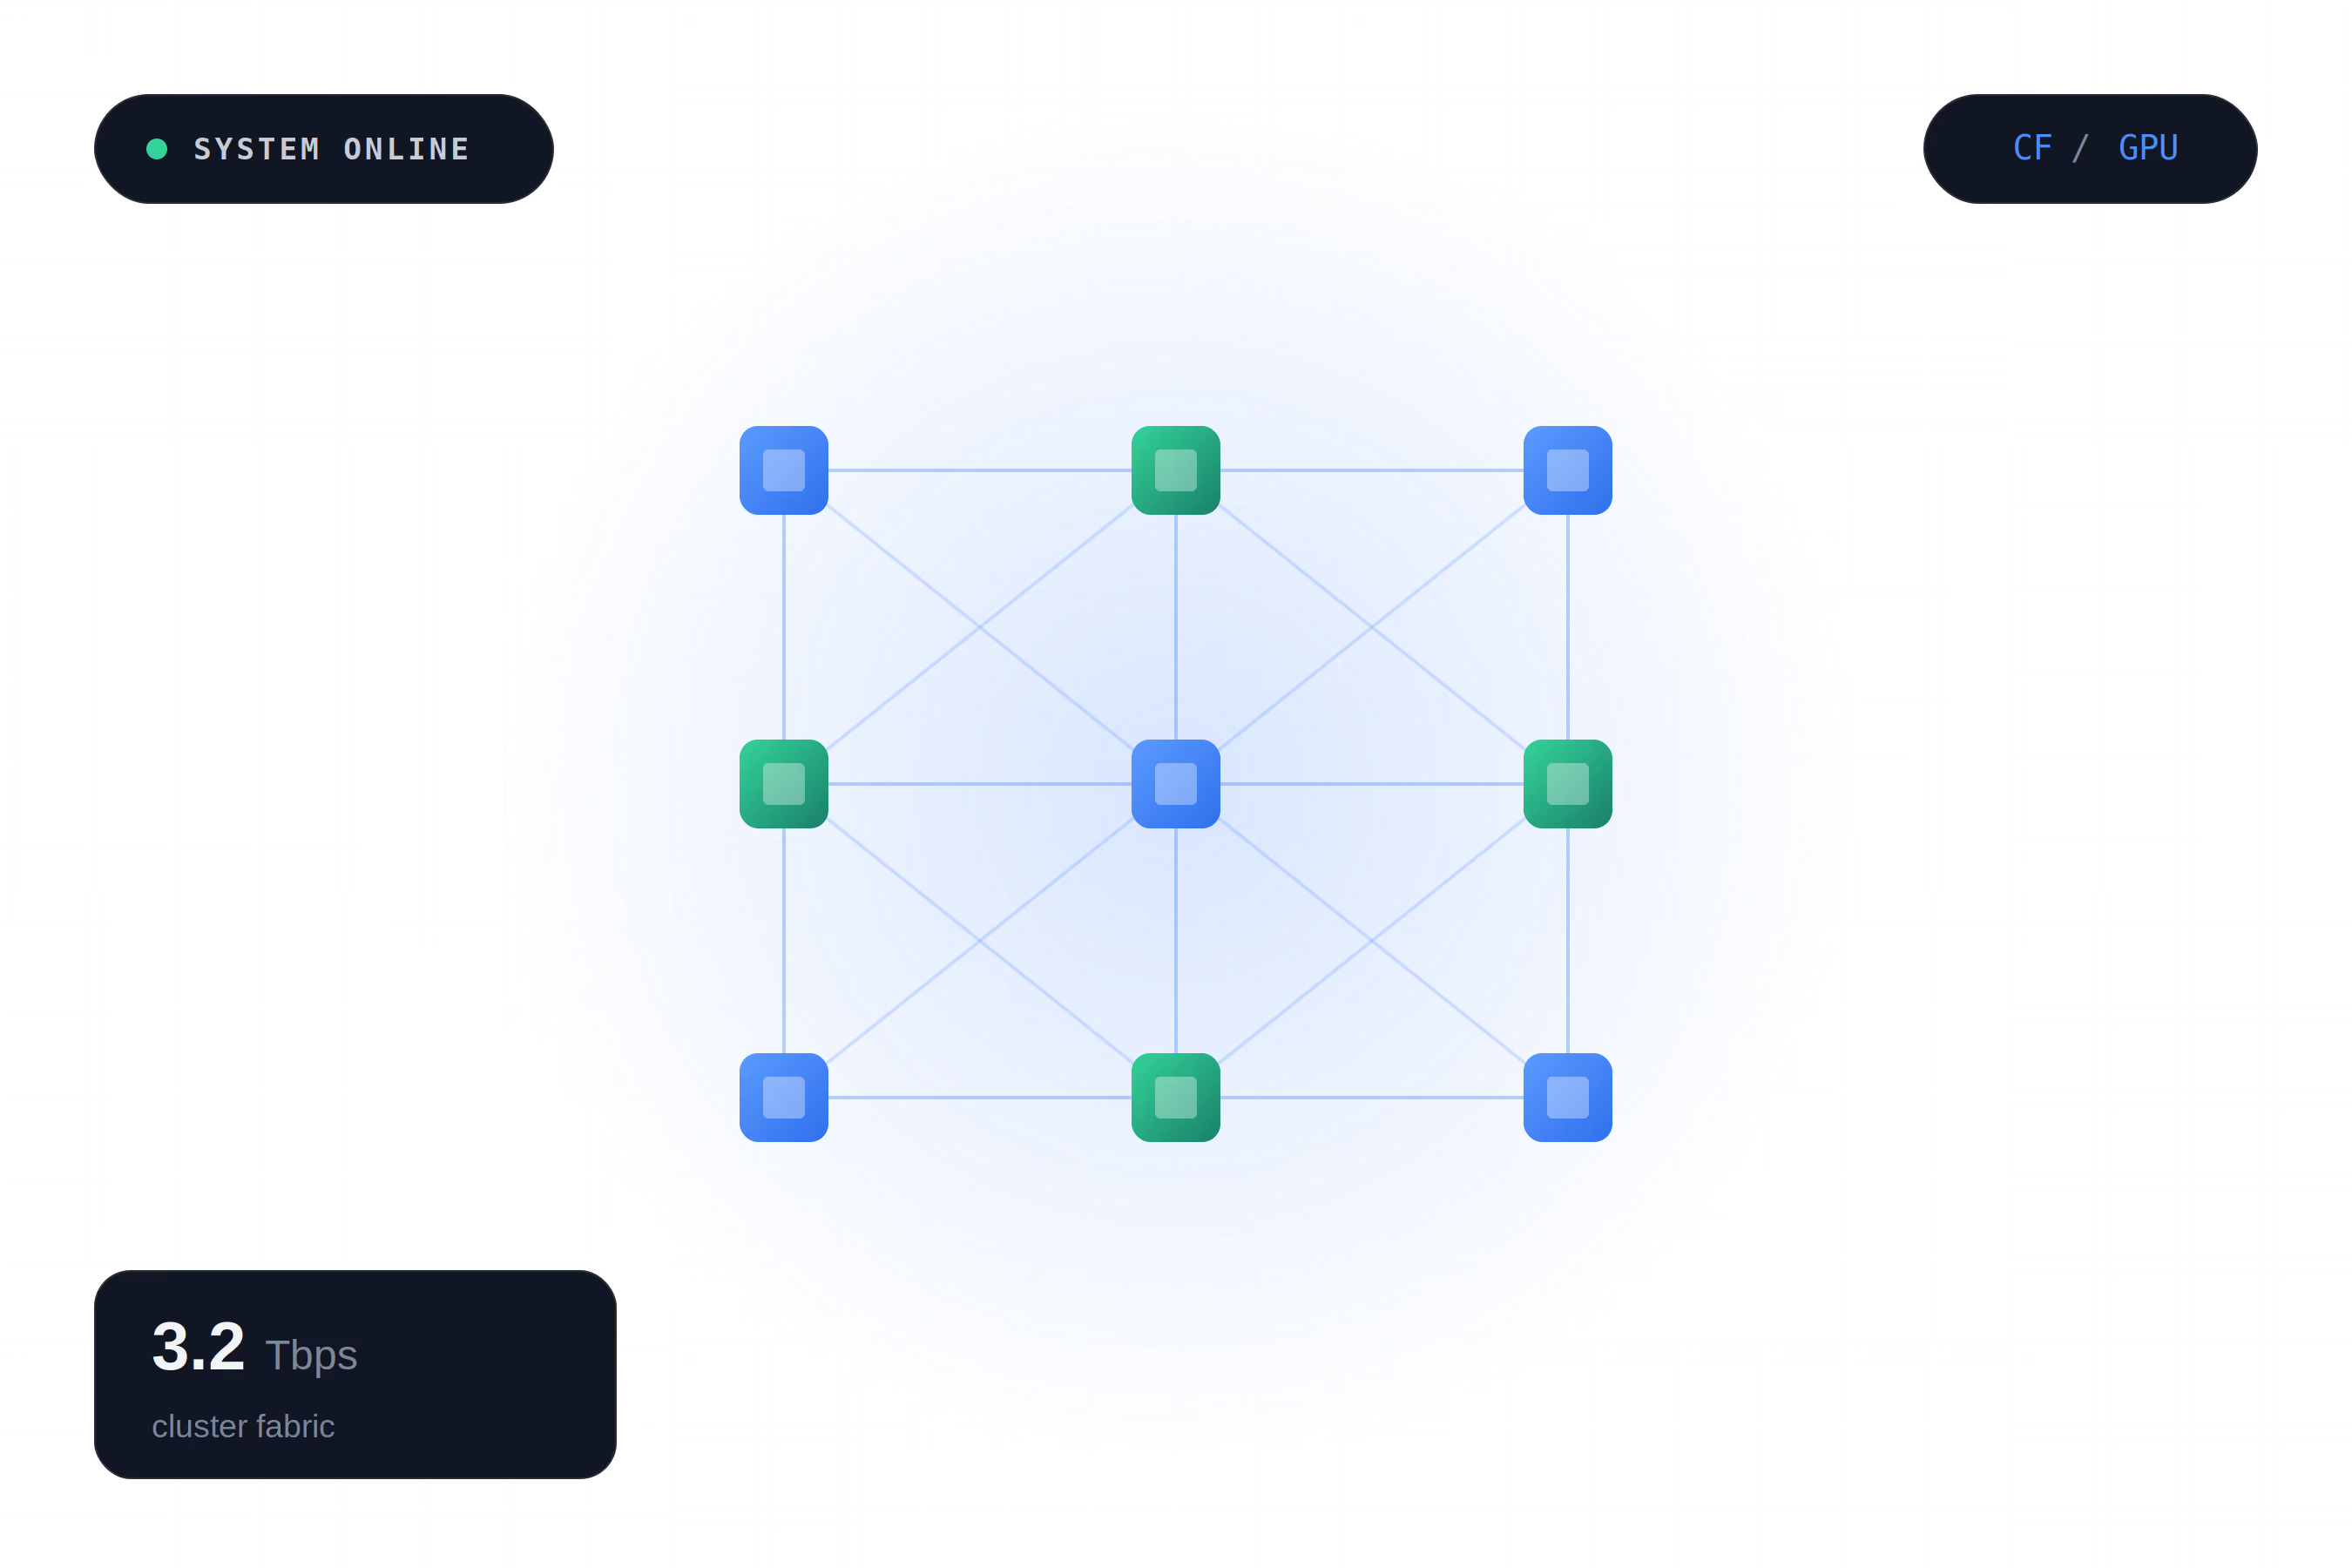
Infrastructure without the operational drag.
The controls your team needs, backed by a platform engineered for predictable performance.
Drivers, topology, scheduling, and health telemetry arrive configured and tested.
Low-latency GPU interconnects keep distributed workloads fed at full throughput.
Parallel storage and object gateways reduce idle time between training runs.
Specialists monitor thermals, fabric health, and accelerator utilization continuously.
Clear capabilities. No fine print.
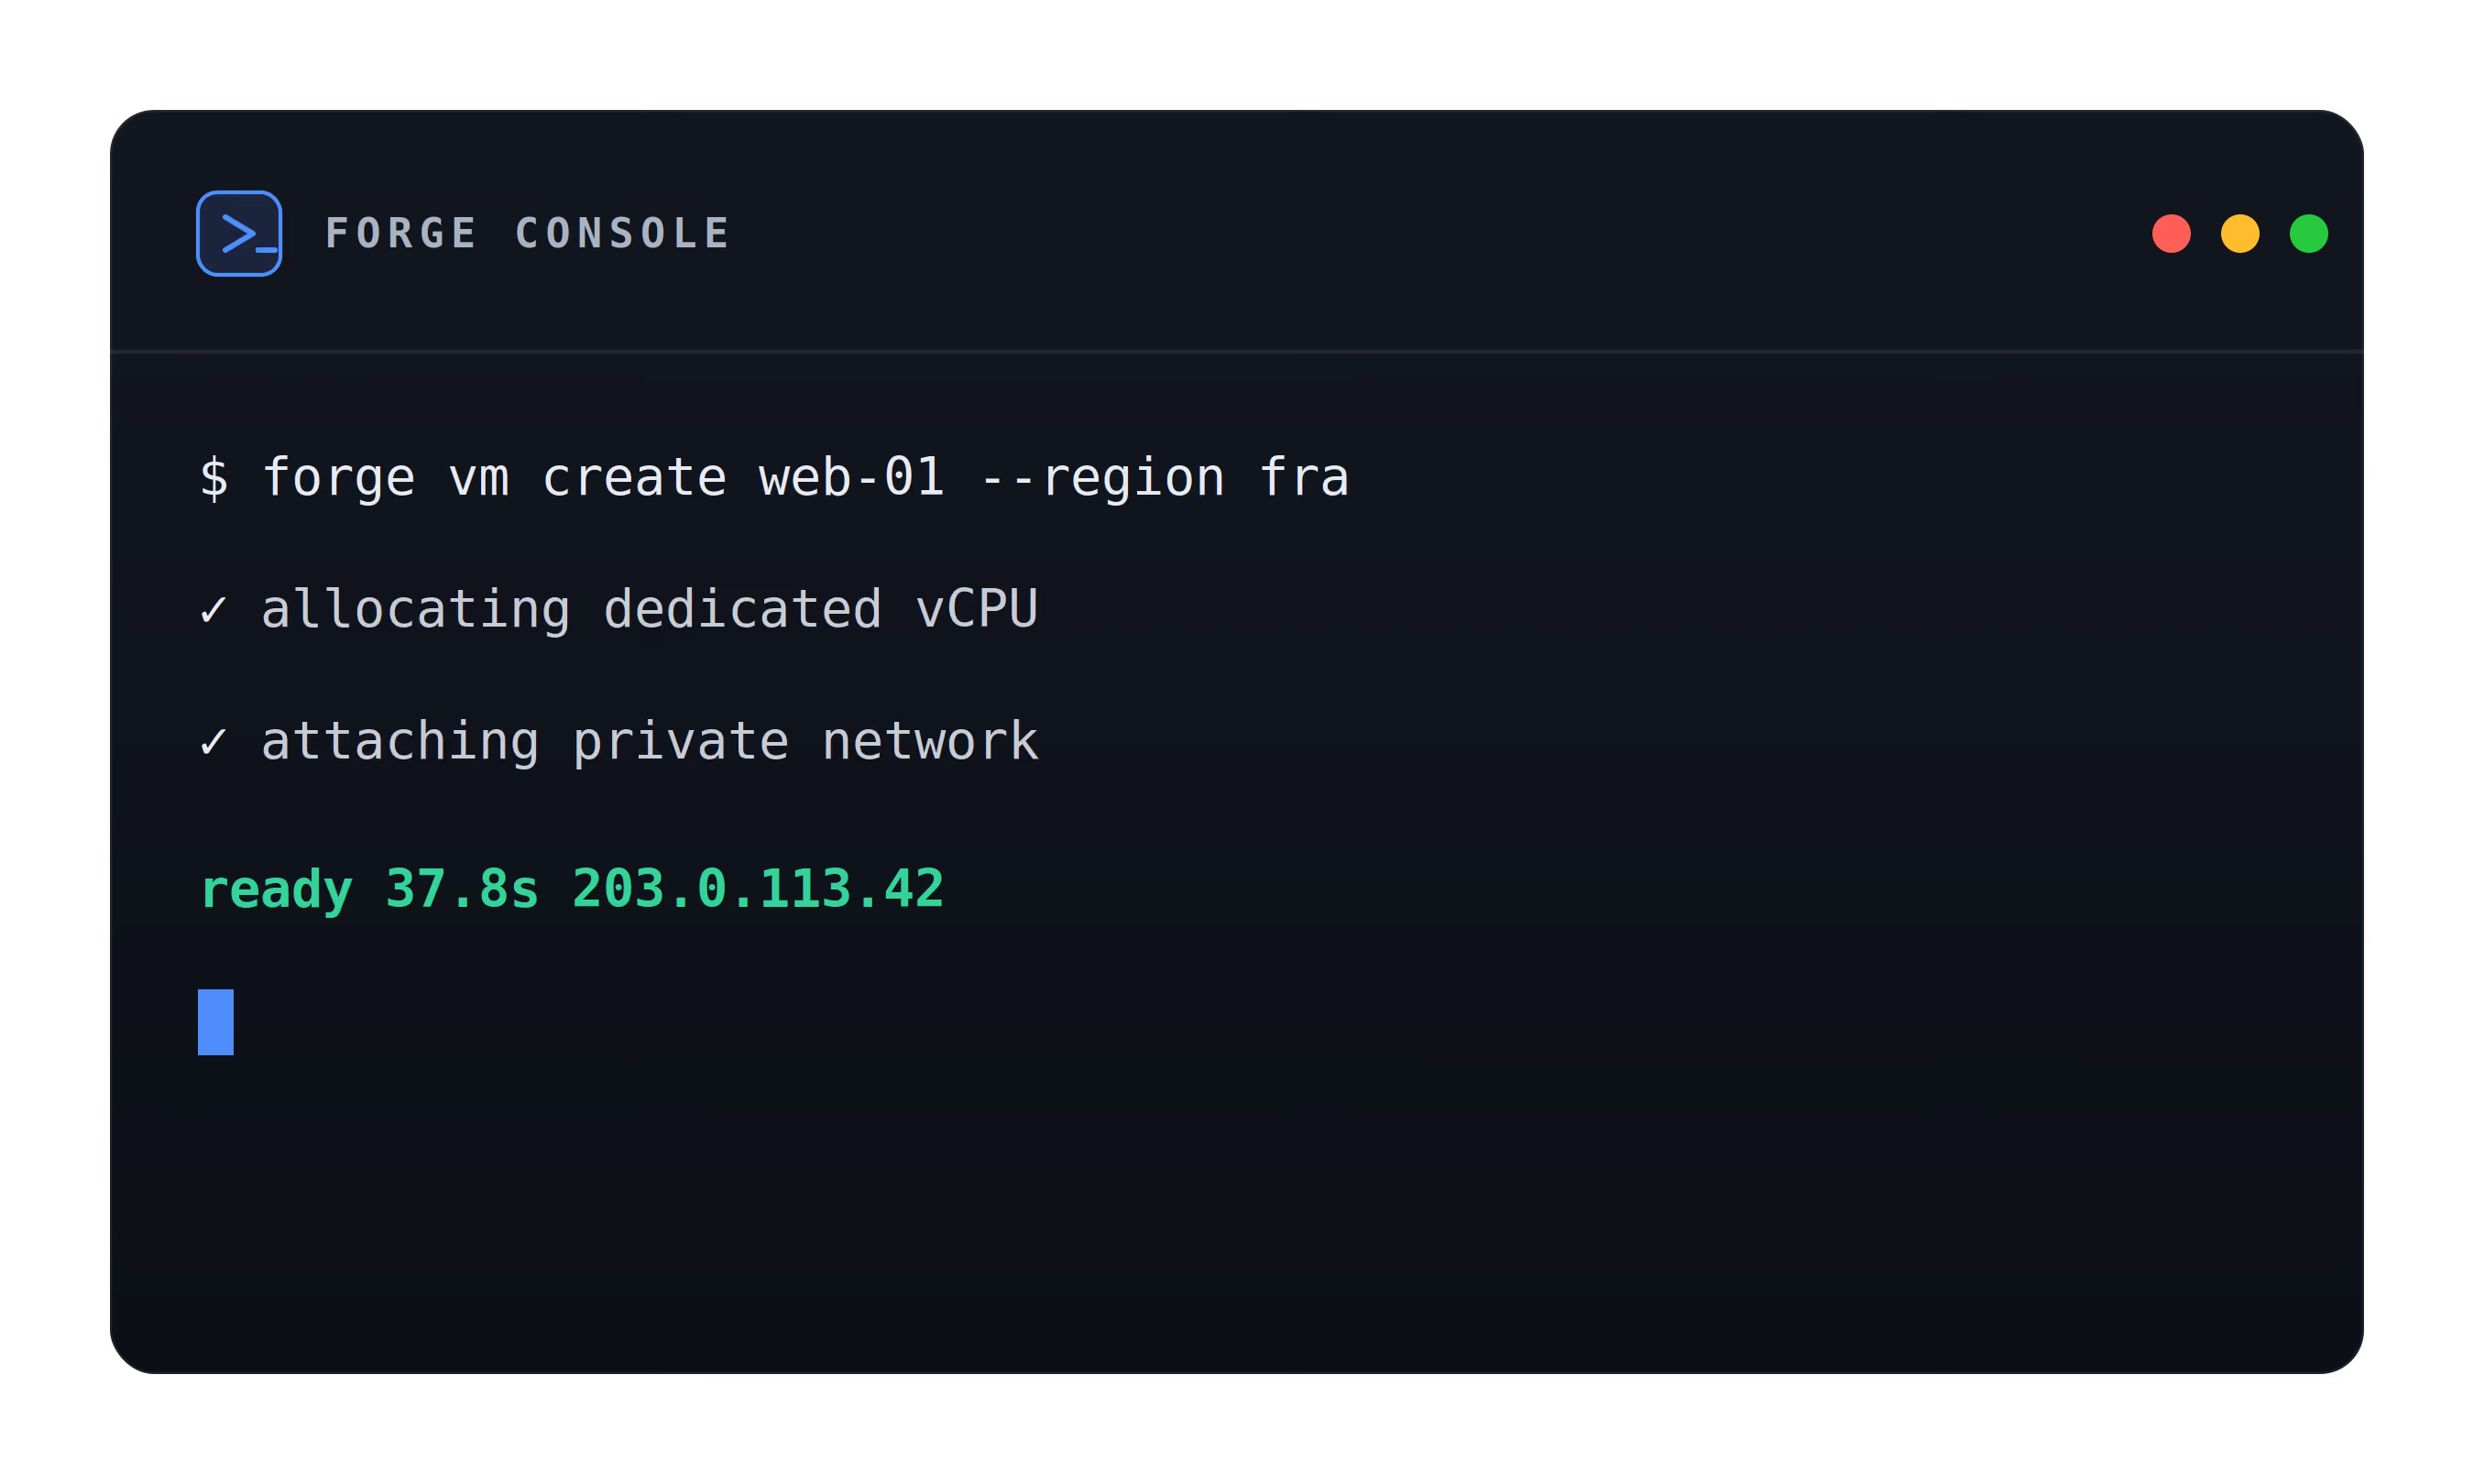
Connect the rest of your stack.
Provision production-ready dedicated servers
with direct hardware access, high-throughput
networking, and remote management
included.
A fully managed, single-tenant cloud built for
regulated workloads, strict data residency, and
enterprise governance
Production GPU clusters for training, inference,
rendering, and simulation, connected by a
high-performance fabric and managed as one
system.